The area of applicability (Meyer & Pebesma 2021, Methods in Ecology and
Evolution 12: 1620–1633, doi:10.1111/2041-210X.13650) is the part of the
predictor space in which a model can be expected to have the cross-validated
accuracy, because new points are not more dissimilar from the training data
than the training points are from each other. This notebook ports the R package
CAST (trainDI(), aoa(); source read at
github779e13f, files R/trainDI.R, R/aoa.R,
R/aoa-helpers.R, R/caret-helpers.R) to Python.
Method, as in the CAST source
Categorical predictors (
.prepare_categorical_variables,.create_dummy_variables): every factor is replaced by one 0/1 dummy per level present in the training data (droplevels,caret::dummyVars, full rank = no). A new point with a level not seen in training gets 0 on every dummy of that variable. Each dummy receives the full weight of its variable (rep(weight, ncol(dummies))), not a share of it. Land cover and biome are integer-coded in our data, so they are declared categorical here.Scaling:
scale()of the (dummy-expanded) training matrix: training mean and sample sd (n − 1); new data are scaled with the same parameters.Weights (
.caret_get_weights):caret::varImp(model, scale = FALSE); for a classification random forest, caret’srfmodule returns the per-class columns ofrandomForest::importance()(permutation mean decrease in accuracy when the forest is grown withimportance = TRUE) and CAST averages them over the classes. Negative weights are set to 0 (.check_weights). Our forests are sklearn forests without OOB permutation importance, so the weight is the permutation decrease in balanced accuracy (= mean over the two classes of the per-class accuracy decrease) on a balanced hold-out drawn from the training pool outside the training draw (as in step 3(c)), 5 repeats.Training DI (
.calc_dist,.mask_dist_mat): for each training point, the Euclidean distance (scaled, weighted space) to the nearest training point in the training part of the CV fold in which the point is held out; the mean distance of each training point to all other training points (no fold masking); DI = nearest distance / mean of those mean distances.Threshold (
.di_threshold): Q3 + 1.5 × IQR of the training DI (Rquantiletype 7 = numpylinear), capped at the maximum training DI.New data (
aoa.data.frame): DI = distance to the nearest of all training points / the same mean distance; inside the AOA if DI ≤ threshold (AOA = ifelse(DI > threshold, 0, 1)). Points with a missing predictor get no DI.
Folds. CAST takes the folds of the model’s cross-validation and recommends
spatial folds when the model is evaluated with spatial CV. Our models were not
fitted by CV, so the folds are defined here: 5-fold GroupKFold by HEALPix cell
(NESTED, WGS84, healpix_geo) at depth 6 (~100 km, used in both step 3(b)
and diagnostic 3) on each model’s own training draw. Sensitivity thresholds:
HEALPix depth 7, random 5-fold, and no CV (useCV = FALSE: nearest other
training point). The DI of new points does not depend on the folds; only the
threshold does.
Models (refitted exactly as in 03_analysis and 03d_transfer_test: same
draws, seed and settings): the step-2 Colombia model, and the diagnostic-3
Neotropical models without and with Colombia.
Applied to: the Colombian prediction grid (1-in-100 systematic 30 m grid of
02b, 2018/2015 inputs, exact WGS84 pixel area × 100), the Colombian validation
points (2000 inputs; 2018 inputs for the non-regrowth comparison with the
authors’ map) and, for the DI–accuracy relationship, the cross-validated
predictions on each model’s training draw with the same HEALPix folds.
The authors’ map. We do not have the authors’ training data, so this notebook cannot compute the authors’ AOA. Section 5 only splits the authors’ published scores by our models’ AOA.
import os
from pathlib import Path

import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
import xarray as xr
from healpix_geo.nested import healpix_to_lonlat, lonlat_to_healpix, vertices
from matplotlib.collections import PolyCollection
from scipy.spatial import cKDTree
from sklearn.ensemble import RandomForestClassifier
from sklearn.inspection import permutation_importance
from sklearn.model_selection import GroupKFold, StratifiedKFold

plt.style.use("seaborn-v0_8-whitegrid")
SMOKE = os.environ.get("SMOKE", "0") == "1"
CLEAN = Path("../data/clean_smoke" if SMOKE else "../data/clean")
RESULTS = Path("../results/smoke" if SMOKE else "../results")
FIGURES = Path("../figures/smoke" if SMOKE else "../figures")
for d in (RESULTS, FIGURES):
d.mkdir(parents=True, exist_ok=True)
N_TREES = 100 if SMOKE else 500
SEED = 20261003
MHA = 1e10
GRID_W = 100
FINAL_VARS = ["forest_density_2000", "dist_forest_2000", "ocdens", "phihox", "pc1", "pc2", "pc3", "pc4", "lc_2000", "biome"]
CAT_VARS = ["lc_2000", "biome"]
PRED_MAP = {"forest_density_2000": "forest_density_2018", "dist_forest_2000": "dist_forest_2018", "lc_2000": "lc_2015"}
VARS_2018 = [PRED_MAP.get(v, v) for v in FINAL_VARS]
COL_SHARE = 188_921 / 4_780_000
N_TRAIN = 2_000 if SMOKE else int(round(1_000_000 * COL_SHARE))
N_HOLDOUT = 1_000 if SMOKE else 10_000
FOLD_DEPTH = 6
N_FOLDS = 5
HP_DEPTH = 8
MODEL_LABELS = {"colombia": "Colombia (step 2)", "neotropics_excl_colombia": "Neotropics excl. Colombia",
"neotropics_incl_colombia": "Neotropics incl. Colombia"}
samples = pd.read_parquet(CLEAN / "samples.parquet")
grid = pd.read_parquet(CLEAN / "pred_grid.parquet")
neo = pd.read_parquet(CLEAN / "neotropics_samples.parquet")
sums = pd.read_csv(CLEAN / "tile_sums.csv").drop(columns="tile").sum()
PI = float(sums["class1_area_ell"] / (sums["class1_area_ell"] + sums["class0_area_ell"]))
print(f"Colombian samples {len(samples):,}; Neotropical samples {len(neo):,}; grid {len(grid):,}; prevalence pi {PI:.5f}")
def make_rf(max_features: int = 3, seed: int = SEED) -> RandomForestClassifier:
"""Identical to 03_analysis.make_rf (R randomForest classification defaults)."""
return RandomForestClassifier(n_estimators=N_TREES, max_features=max_features, min_samples_leaf=1, bootstrap=True,
oob_score=True, n_jobs=-1, random_state=seed)
def balanced_train(pool: pd.DataFrame, n: int = N_TRAIN, seed: int = SEED) -> pd.DataFrame:
return pd.concat([g.sample(n=min(n // 2, len(g)), random_state=seed) for _, g in pool.groupby("label")])
def prior_shift(p: np.ndarray, pi: float = PI, train_prev: float = 0.5) -> np.ndarray:
num = p * pi / train_prev
return num / (num + (1 - p) * (1 - pi) / (1 - train_prev))Colombian samples 275,336; Neotropical samples 69,400; grid 12,161,726; prevalence pi 0.01644
1. Models and training draws (as in 03 and 03d)
col_pool = samples[samples.set == "train_pool"]
col_val = samples[samples.set == "validation"].reset_index(drop=True)
val_key = set(zip(col_val.grow, col_val.gcol))
neo_pool = neo[(neo.set == "train_pool") & ~pd.Series(list(zip(neo.grow, neo.gcol)), index=neo.index).isin(val_key)]
TRAIN = {
    "colombia": pd.concat([g.sample(n=min(N_TRAIN // 2, len(g)), random_state=SEED) for _, g in col_pool.groupby("label")]),
    "neotropics_excl_colombia": balanced_train(neo_pool[~neo_pool.in_colombia]),
    "neotropics_incl_colombia": balanced_train(neo_pool),
}
HOLDOUT_POOL = {"colombia": col_pool, "neotropics_excl_colombia": neo_pool[~neo_pool.in_colombia],
                "neotropics_incl_colombia": neo_pool}
MODELS = {k: make_rf().fit(t[FINAL_VARS].to_numpy(), t.label.to_numpy()) for k, t in TRAIN.items()}
y_val = col_val.label.to_numpy()
P_VAL = {k: m.predict_proba(col_val[FINAL_VARS].to_numpy())[:, 1] for k, m in MODELS.items()}
for k in MODELS:
    print(f"{k:26s} n_train {len(TRAIN[k]):,}  Colombian validation accuracy {((P_VAL[k] > 0.5) == y_val).mean():.4f}")
colombia n_train 39,522 Colombian validation accuracy 0.8867
neotropics_excl_colombia n_train 39,522 Colombian validation accuracy 0.7671
neotropics_incl_colombia n_train 39,522 Colombian validation accuracy 0.7835
2. Variable weights (permutation importance, CAST / caret convention)
WEIGHTS = {}
for k, m in MODELS.items():
    rest = HOLDOUT_POOL[k].drop(TRAIN[k].index)
    if rest.label.nunique() < 2:  # smoke test only: the whole pool is in the training draw
        print(f"{k}: no hold-out records left, importance on the training draw")
        rest = TRAIN[k]
    ho = balanced_train(rest, N_HOLDOUT, SEED + 100)
    pi_ = permutation_importance(m, ho[FINAL_VARS].to_numpy(), ho.label.to_numpy(), scoring="balanced_accuracy",
                                 n_repeats=5, random_state=SEED, n_jobs=-1)
    WEIGHTS[k] = pd.Series(np.maximum(pi_.importances_mean, 0.0), index=FINAL_VARS)  # CAST: negative -> 0
weights = pd.DataFrame(WEIGHTS)
print(weights.round(4).to_string())
colombia neotropics_excl_colombia neotropics_incl_colombia
forest_density_2000 0.0619 0.0586 0.0602
dist_forest_2000 0.1607 0.2527 0.2559
ocdens 0.0264 0.0112 0.0160
phihox 0.0474 0.0169 0.0208
pc1 0.0207 0.0274 0.0230
pc2 0.0099 0.0235 0.0255
pc3 0.0202 0.0198 0.0213
pc4 0.0234 0.0297 0.0280
lc_2000 0.0077 0.0145 0.0145
biome 0.0022 0.0012 0.0022
3. AOA functions (port of CAST trainDI() / aoa())
class AOA:
    """CAST trainDI + aoa, Euclidean distance, categorical variables as full-weight dummies."""

    def __init__(self, train: pd.DataFrame, weight: pd.Series, folds: dict[str, np.ndarray]) -> None:
        self.levels = {v: np.sort(train[v].dropna().unique()) for v in CAT_VARS}
        X = self._expand(train[FINAL_VARS])
        w = np.concatenate([[weight[v]] for v in FINAL_VARS if v not in CAT_VARS]
                           + [np.full(len(self.levels[v]), weight[v]) for v in CAT_VARS])
        self.center = X.mean(axis=0)
        self.scale = X.std(axis=0, ddof=1)
        self.keep = self.scale > 0  # CAST stops on zero-variance columns; only possible in the smoke test
        if not self.keep.all():
            print("dropping zero-variance columns:", np.array(self.colnames)[~self.keep].tolist())
        self.w = w[self.keep]
        self.Xt = self._transform(X)
        self.tree = cKDTree(self.Xt)
        self.mean_dist = self._mean_pairwise()
        self.train_di = {name: self._cv_nearest(f) / self.mean_dist for name, f in folds.items()}
        self.thresholds = {name: di_threshold(di) for name, di in self.train_di.items()}

    def _expand(self, df: pd.DataFrame) -> np.ndarray:
        num = [v for v in FINAL_VARS if v not in CAT_VARS]
        cols = [df[v].to_numpy(dtype=float) for v in num]
        self.colnames = list(num)
        for v in CAT_VARS:
            x = df[v].to_numpy(dtype=float)
            for lev in self.levels[v]:
                cols.append((x == lev).astype(float))  # unseen level or NaN -> 0 on every dummy, as in CAST
                self.colnames.append(f"{v}_{lev:g}")
        return np.column_stack(cols)

    def _transform(self, X: np.ndarray) -> np.ndarray:
        return ((X - self.center) / np.where(self.scale > 0, self.scale, 1.0))[:, self.keep] * self.w

    def _mean_pairwise(self, batch: int = 2048) -> float:
        X = self.Xt
        n = len(X)
        sq = (X**2).sum(axis=1)
        row_mean = np.empty(n)
        for i in range(0, n, batch):
            q = X[i:i + batch]
            d = np.sqrt(np.maximum(sq[i:i + batch, None] - 2 * q @ X.T + sq[None, :], 0.0))
            d[np.arange(len(q)), np.arange(i, i + len(q))] = 0.0  # self-distance excluded
            row_mean[i:i + batch] = d.sum(axis=1) / (n - 1)
        return float(row_mean.mean())

    def _cv_nearest(self, fold: np.ndarray | None) -> np.ndarray:
        X = self.Xt
        out = np.empty(len(X))
        if fold is None:  # useCV = FALSE: nearest other training point (self masked by index only)
            d, idx = self.tree.query(X, k=2, workers=-1)
            self_first = idx[:, 0] == np.arange(len(X))
            return np.where(self_first, d[:, 1], d[:, 0])
        for f in np.unique(fold):
            te = fold == f
            out[te] = cKDTree(X[~te]).query(X[te], workers=-1)[0]
        return out

    def di(self, df: pd.DataFrame, batch: int = 500_000) -> np.ndarray:
        """DI of new data (columns named as FINAL_VARS); NaN where a predictor is missing."""
        out = np.full(len(df), np.nan)
        ok = ~df[FINAL_VARS].isna().any(axis=1).to_numpy()
        idx = np.flatnonzero(ok)
        for i in range(0, len(idx), batch):
            j = idx[i:i + batch]
            out[j] = self.tree.query(self._transform(self._expand(df.iloc[j])), workers=-1)[0] / self.mean_dist
        return out


def di_threshold(train_di: np.ndarray) -> float:
    """CAST .di_threshold: Q3 + 1.5 IQR, capped at the maximum training DI."""
    q1, q3 = np.nanquantile(train_di, [0.25, 0.75])
    return float(min(q3 + 1.5 * (q3 - q1), np.nanmax(train_di)))


def make_folds(t: pd.DataFrame) -> dict[str, np.ndarray | None]:
    y = t.label.to_numpy()
    out: dict[str, np.ndarray | None] = {}
    for depth in (FOLD_DEPTH, FOLD_DEPTH + 1):
        cells = lonlat_to_healpix(t.lon.to_numpy(), t.lat.to_numpy(), depth, ellipsoid="WGS84")
        k = min(N_FOLDS, len(np.unique(cells)))
        f = np.empty(len(t), dtype=int)
        for i, (_, te) in enumerate(GroupKFold(k).split(y, y, groups=cells)):
            f[te] = i
        out[f"healpix_d{depth}"] = f
    f = np.empty(len(t), dtype=int)
    for i, (_, te) in enumerate(StratifiedKFold(N_FOLDS, shuffle=True, random_state=SEED).split(y, y)):
        f[te] = i
    out["random_5fold"] = f
    out["none"] = None
    return out


PRIMARY = f"healpix_d{FOLD_DEPTH}"
FOLDS = {k: make_folds(t.reset_index(drop=True)) for k, t in TRAIN.items()}
AOAS = {k: AOA(TRAIN[k].reset_index(drop=True), WEIGHTS[k], FOLDS[k]) for k in MODELS}
for k, a in AOAS.items():
    di = a.train_di[PRIMARY]
    print(f"{k:26s} dims {a.Xt.shape[1]}  mean pairwise distance {a.mean_dist:.4f}  "
          f"training DI median {np.median(di):.4f}  thresholds "
          + ", ".join(f"{n} {t:.4f}" for n, t in a.thresholds.items()))
colombia dims 19 mean pairwise distance 0.1943 training DI median 0.0799 thresholds healpix_d6 0.1979, healpix_d7 0.1914, random_5fold 0.1792, none 0.1720
neotropics_excl_colombia dims 22 mean pairwise distance 0.2006 training DI median 0.0619 thresholds healpix_d6 0.1630, healpix_d7 0.1454, random_5fold 0.1315, none 0.1249
neotropics_incl_colombia dims 22 mean pairwise distance 0.2053 training DI median 0.0692 thresholds healpix_d6 0.1837, healpix_d7 0.1626, random_5fold 0.1483, none 0.1412
4. DI on the Colombian prediction grid and validation points
g = grid[grid.is_pred_domain].copy()
Xg = g[VARS_2018].rename(columns={v18: v for v, v18 in zip(FINAL_VARS, VARS_2018)})
ok = ~Xg.isna().any(axis=1).to_numpy()
area_incomplete = float((g.area_ell[~ok] * GRID_W).sum() / MHA)
g, Xg = g[ok].copy(), Xg[ok]
a_grid = g.area_ell.to_numpy() * GRID_W
auth_p = np.where(g.auth_pct.to_numpy() <= 100, g.auth_pct.to_numpy(), 0) / 100  # NoData = 0, as in 03d
print(f"grid points with complete predictors {len(g):,}; prediction-domain area without complete predictors "
      f"{area_incomplete:.4f} Mha (no DI, excluded)")

nr = col_val[col_val.label == 0].reset_index(drop=True)
nr18 = nr[VARS_2018].rename(columns={v18: v for v, v18 in zip(FINAL_VARS, VARS_2018)})
DI_GRID, DI_VAL, DI_NR18, P_GRID, P_NR18 = {}, {}, {}, {}, {}
for k, m in MODELS.items():
    DI_GRID[k] = AOAS[k].di(Xg)
    DI_VAL[k] = AOAS[k].di(col_val)
    DI_NR18[k] = AOAS[k].di(nr18)
    P_GRID[k] = m.predict_proba(Xg.to_numpy())[:, 1]
    P_NR18[k] = m.predict_proba(nr18.to_numpy())[:, 1]
    print(f"{k:26s} grid DI median {np.median(DI_GRID[k]):.4f}; share of grid area outside AOA "
          f"{(a_grid * (DI_GRID[k] > AOAS[k].thresholds[PRIMARY])).sum() / a_grid.sum():.4f}")
grid points with complete predictors 2,456,636; prediction-domain area without complete predictors 0.0915 Mha (no DI, excluded)
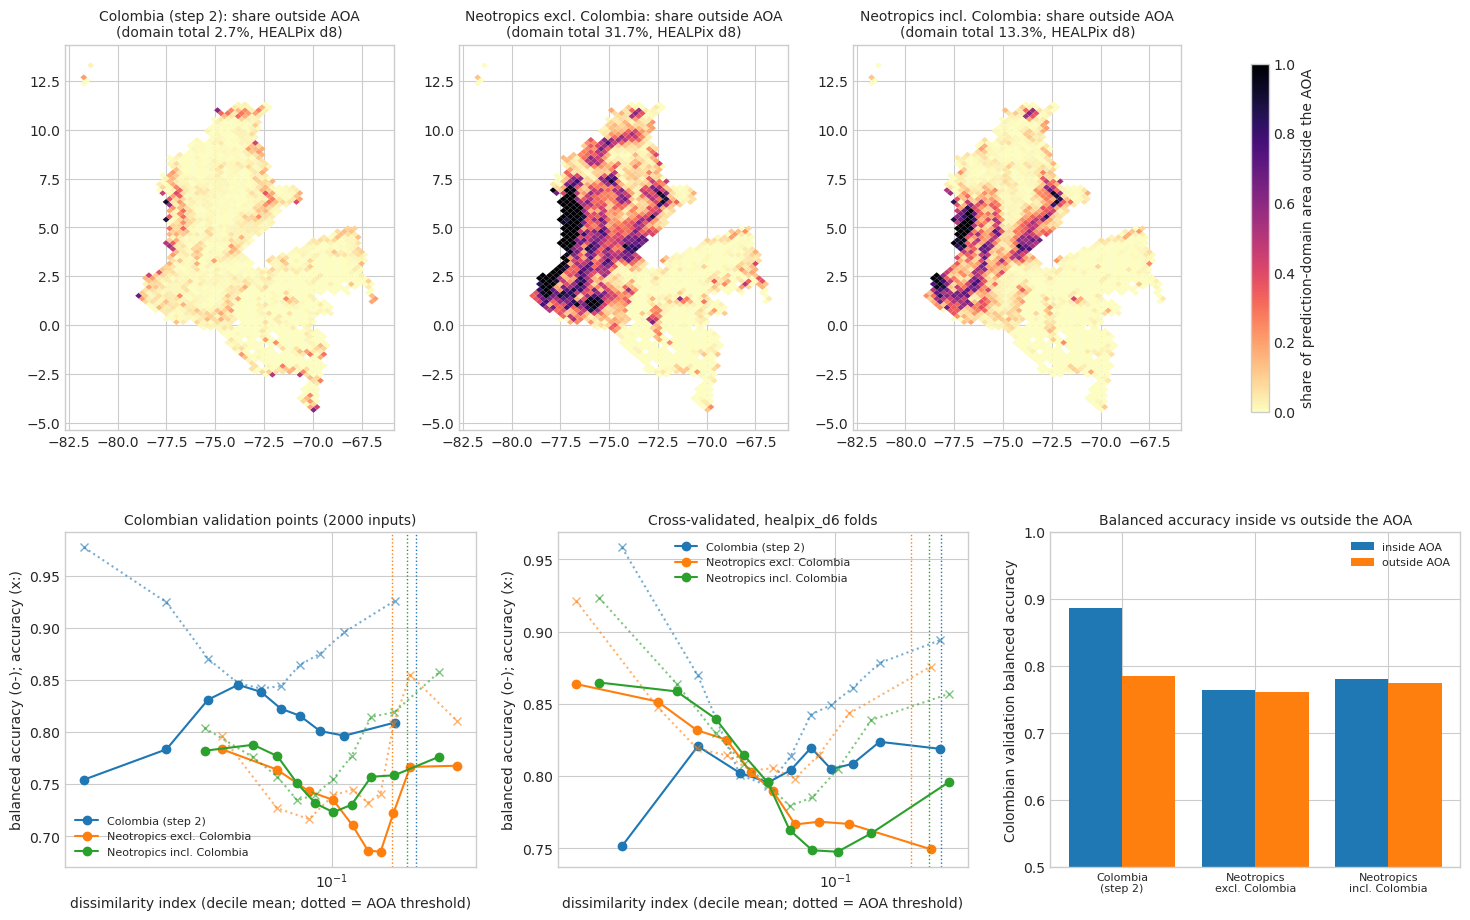
colombia grid DI median 0.0812; share of grid area outside AOA 0.0267
neotropics_excl_colombia grid DI median 0.1382; share of grid area outside AOA 0.3174
neotropics_incl_colombia grid DI median 0.1085; share of grid area outside AOA 0.1330
5. Summary: inside vs outside each model’s AOA
Rows for every threshold variant (cv_folds); healpix_d6 is the primary one.
inside / outside / all hold the metric on the respective subset. The
authors’ rows split the authors’ published scores by our model’s AOA;
they are not the authors’ AOA.
rows = []


def add(model: str, folds: str, metric: str, inside: float, outside: float, total: float, unit: str,
        note: str = "") -> None:
    rows.append(dict(model=model, cv_folds=folds, metric=metric, inside=inside, outside=outside, all=total,
                     unit=unit, note=note))


def split_sum(x: np.ndarray, inside: np.ndarray, scale: float = MHA) -> tuple[float, float, float]:
    return float(x[inside].sum() / scale), float(x[~inside].sum() / scale), float(x.sum() / scale)


def class_acc(correct: np.ndarray, y: np.ndarray) -> dict[str, float]:
    a1 = float(correct[y == 1].mean()) if (y == 1).any() else np.nan
    a0 = float(correct[y == 0].mean()) if (y == 0).any() else np.nan
    return {"accuracy": float(correct.mean()) if len(y) else np.nan, "accuracy_regrowth": a1,
            "accuracy_nonregrowth": a0, "balanced_accuracy": np.nanmean([a1, a0]) if len(y) else np.nan}


def split_mean(x: np.ndarray, inside: np.ndarray) -> tuple[float, float, float]:
    f = lambda s: float(x[s].mean()) if s.any() else np.nan  # noqa: E731
    return f(inside), f(~inside), float(x.mean())


nr_auth_ok = (nr.auth_pct <= 100).to_numpy()
nr_auth = nr.auth_pct.to_numpy() / 100
DI_NR00 = {k: DI_VAL[k][(col_val.label == 0).to_numpy()] for k in MODELS}
for k, a in AOAS.items():
    for folds, thr in a.thresholds.items():
        tdi = a.train_di[folds]
        q1, q3 = np.quantile(tdi, [0.25, 0.75])
        add(k, folds, "threshold", np.nan, np.nan, thr, "DI", "CAST: min(Q3 + 1.5 IQR, max) of the CV training DI")
        add(k, folds, "train_di_median", np.nan, np.nan, float(np.median(tdi)), "DI")
        add(k, folds, "train_di_q3", np.nan, np.nan, float(q3), "DI")
        add(k, folds, "train_di_iqr", np.nan, np.nan, float(q3 - q1), "DI")
        add(k, folds, "train_di_max", np.nan, np.nan, float(tdi.max()), "DI")
        add(k, folds, "share_training_outside", np.nan, np.nan, float((tdi > thr).mean()), "fraction")
        add(k, folds, "mean_pairwise_distance", np.nan, np.nan, a.mean_dist, "scaled weighted units")
        ins = DI_GRID[k] <= thr
        add(k, folds, "pred_domain_area_mha", *split_sum(a_grid, ins), "Mha",
            f"exact WGS84 area of 1-in-100 grid points x 100; {area_incomplete:.4f} Mha without complete predictors "
            "excluded")
        i_, o_, t_ = split_sum(a_grid, ins, 1.0)
        add(k, folds, "pred_domain_area_share", i_ / t_, o_ / t_, 1.0, "fraction")
        add(k, folds, "expected_area_uncal_mha", *split_sum(P_GRID[k] * a_grid, ins), "Mha", "sum p x area (paper)")
        add(k, folds, "expected_area_prior_shift_mha", *split_sum(prior_shift(P_GRID[k]) * a_grid, ins), "Mha",
            f"prior-shift to Colombian prevalence {PI:.5f}")
        add(k, folds, "area_p_gt05_uncal_mha", *split_sum((P_GRID[k] > 0.5) * a_grid, ins), "Mha")
        add(k, folds, "mean_p_grid_area_weighted",
            *(s / w for s, w in zip(split_sum(P_GRID[k] * a_grid, ins, 1.0), split_sum(a_grid, ins, 1.0))), "p")
        add(k, folds, "authors_expected_area_mha", *split_sum(auth_p * a_grid, ins), "Mha",
            "authors' published map split by OUR model's AOA (not the authors' AOA); NoData = 0")
        add(k, folds, "authors_area_pct_gt50_mha", *split_sum((auth_p > 0.5) * a_grid, ins), "Mha",
            "authors' map split by OUR model's AOA")
        iv = DI_VAL[k] <= thr
        corr = (P_VAL[k] > 0.5) == y_val
        add(k, folds, "validation_accuracy_2000", *split_mean(corr.astype(float), iv), "fraction",
            "Colombian validation points, 2000 inputs; class mix differs inside/outside, see balanced accuracy")
        for key in ["accuracy_regrowth", "accuracy_nonregrowth", "balanced_accuracy"]:
            add(k, folds, f"validation_{key}_2000", class_acc(corr[iv], y_val[iv])[key],
                class_acc(corr[~iv], y_val[~iv])[key], class_acc(corr, y_val)[key], "fraction",
                "Colombian validation points, 2000 inputs")
        add(k, folds, "validation_n", float(iv.sum()), float((~iv).sum()), float(len(iv)), "points")
        add(k, folds, "validation_share_regrowth", *split_mean(y_val.astype(float), iv), "fraction")
        for yr, di_nr, p_nr in [("2000", DI_NR00[k], P_VAL[k][y_val == 0]), ("2018", DI_NR18[k], P_NR18[k])]:
            inr = di_nr <= thr
            add(k, folds, f"nonregrowth_n_{yr}", float(inr.sum()), float((~inr).sum()), float(len(inr)), "points",
                f"Colombian non-regrowth validation points, AOA from {yr} inputs")
            add(k, folds, f"nonregrowth_mean_p_model_{yr}", *split_mean(p_nr, inr), "p", f"{yr} inputs")
            add(k, folds, f"nonregrowth_share_gt05_model_{yr}", *split_mean((p_nr > 0.5).astype(float), inr),
                "fraction", f"{yr} inputs")
            ia = inr[nr_auth_ok]
            add(k, folds, f"nonregrowth_mean_p_authors_aoa{yr}", *split_mean(nr_auth[nr_auth_ok], ia), "p",
                f"authors' score (pct/100, NoData excluded) split by OUR AOA from {yr} inputs; not the authors' AOA")
            add(k, folds, f"nonregrowth_share_gt05_authors_aoa{yr}",
                *split_mean((nr_auth[nr_auth_ok] > 0.5).astype(float), ia), "fraction",
                f"authors' score split by OUR AOA from {yr} inputs; not the authors' AOA")
summary = pd.DataFrame(rows)
summary.to_csv(RESULTS / "aoa_summary.csv", index=False)
with pd.option_context("display.width", 250, "display.max_rows", 500, "display.max_colwidth", 40):
    print(summary[summary.cv_folds == PRIMARY].drop(columns=["cv_folds", "note"])
          .to_string(index=False, float_format=lambda v: f"{v:.4f}"))
model metric inside outside all unit
colombia threshold NaN NaN 0.1979 DI
colombia train_di_median NaN NaN 0.0799 DI
colombia train_di_q3 NaN NaN 0.1116 DI
colombia train_di_iqr NaN NaN 0.0575 DI
colombia train_di_max NaN NaN 3.2022 DI
colombia share_training_outside NaN NaN 0.0302 fraction
colombia mean_pairwise_distance NaN NaN 0.1943 scaled weighted units
colombia pred_domain_area_mha 18.2849 0.5014 18.7863 Mha
colombia pred_domain_area_share 0.9733 0.0267 1.0000 fraction
colombia expected_area_uncal_mha 3.9282 0.0605 3.9887 Mha
colombia expected_area_prior_shift_mha 0.1867 0.0015 0.1883 Mha
colombia area_p_gt05_uncal_mha 2.0114 0.0145 2.0259 Mha
colombia mean_p_grid_area_weighted 0.2148 0.1207 0.2123 p
colombia authors_expected_area_mha 10.1754 0.1751 10.3505 Mha
colombia authors_area_pct_gt50_mha 10.9614 0.1232 11.0846 Mha
colombia validation_accuracy_2000 0.8859 0.9367 0.8867 fraction
colombia validation_accuracy_regrowth_2000 0.8540 0.5830 0.8530 fraction
colombia validation_accuracy_nonregrowth_2000 0.9185 0.9872 0.9204 fraction
colombia validation_balanced_accuracy_2000 0.8863 0.7851 0.8867 fraction
colombia validation_n 121476.0000 1880.0000 123356.0000 points
colombia validation_share_regrowth 0.5058 0.1250 0.5000 fraction
colombia nonregrowth_n_2000 60033.0000 1645.0000 61678.0000 points
colombia nonregrowth_mean_p_model_2000 0.1891 0.0950 0.1865 p
colombia nonregrowth_share_gt05_model_2000 0.0815 0.0128 0.0796 fraction
colombia nonregrowth_mean_p_authors_aoa2000 0.5243 0.3181 0.5188 p
colombia nonregrowth_share_gt05_authors_aoa2000 0.5355 0.1887 0.5263 fraction
colombia nonregrowth_n_2018 59679.0000 1999.0000 61678.0000 points
colombia nonregrowth_mean_p_model_2018 0.1691 0.1191 0.1675 p
colombia nonregrowth_share_gt05_model_2018 0.0591 0.0185 0.0578 fraction
colombia nonregrowth_mean_p_authors_aoa2018 0.5242 0.3574 0.5188 p
colombia nonregrowth_share_gt05_authors_aoa2018 0.5353 0.2578 0.5263 fraction
neotropics_excl_colombia threshold NaN NaN 0.1630 DI
neotropics_excl_colombia train_di_median NaN NaN 0.0619 DI
neotropics_excl_colombia train_di_q3 NaN NaN 0.0896 DI
neotropics_excl_colombia train_di_iqr NaN NaN 0.0489 DI
neotropics_excl_colombia train_di_max NaN NaN 31.8635 DI
neotropics_excl_colombia share_training_outside NaN NaN 0.0367 fraction
neotropics_excl_colombia mean_pairwise_distance NaN NaN 0.2006 scaled weighted units
neotropics_excl_colombia pred_domain_area_mha 12.8229 5.9634 18.7863 Mha
neotropics_excl_colombia pred_domain_area_share 0.6826 0.3174 1.0000 fraction
neotropics_excl_colombia expected_area_uncal_mha 3.2382 1.2104 4.4486 Mha
neotropics_excl_colombia expected_area_prior_shift_mha 0.0868 0.0292 0.1159 Mha
neotropics_excl_colombia area_p_gt05_uncal_mha 0.7512 0.1250 0.8762 Mha
neotropics_excl_colombia mean_p_grid_area_weighted 0.2525 0.2030 0.2368 p
neotropics_excl_colombia authors_expected_area_mha 7.5641 2.7864 10.3505 Mha
neotropics_excl_colombia authors_area_pct_gt50_mha 8.5080 2.5766 11.0846 Mha
neotropics_excl_colombia validation_accuracy_2000 0.7447 0.8306 0.7671 fraction
neotropics_excl_colombia validation_accuracy_regrowth_2000 0.5874 0.5400 0.5789 fraction
neotropics_excl_colombia validation_accuracy_nonregrowth_2000 0.9410 0.9827 0.9552 fraction
neotropics_excl_colombia validation_balanced_accuracy_2000 0.7642 0.7613 0.7671 fraction
neotropics_excl_colombia validation_n 91256.0000 32100.0000 123356.0000 points
neotropics_excl_colombia validation_share_regrowth 0.5551 0.3435 0.5000 fraction
neotropics_excl_colombia nonregrowth_n_2000 40604.0000 21074.0000 61678.0000 points
neotropics_excl_colombia nonregrowth_mean_p_model_2000 0.2457 0.1957 0.2286 p
neotropics_excl_colombia nonregrowth_share_gt05_model_2000 0.0590 0.0173 0.0448 fraction
neotropics_excl_colombia nonregrowth_mean_p_authors_aoa2000 0.5545 0.4502 0.5188 p
neotropics_excl_colombia nonregrowth_share_gt05_authors_aoa2000 0.5971 0.3902 0.5263 fraction
neotropics_excl_colombia nonregrowth_n_2018 39431.0000 22247.0000 61678.0000 points
neotropics_excl_colombia nonregrowth_mean_p_model_2018 0.2321 0.1921 0.2177 p
neotropics_excl_colombia nonregrowth_share_gt05_model_2018 0.0437 0.0219 0.0358 fraction
neotropics_excl_colombia nonregrowth_mean_p_authors_aoa2018 0.5564 0.4523 0.5188 p
neotropics_excl_colombia nonregrowth_share_gt05_authors_aoa2018 0.6002 0.3956 0.5263 fraction
neotropics_incl_colombia threshold NaN NaN 0.1837 DI
neotropics_incl_colombia train_di_median NaN NaN 0.0692 DI
neotropics_incl_colombia train_di_q3 NaN NaN 0.1011 DI
neotropics_incl_colombia train_di_iqr NaN NaN 0.0550 DI
neotropics_incl_colombia train_di_max NaN NaN 14.0643 DI
neotropics_incl_colombia share_training_outside NaN NaN 0.0507 fraction
neotropics_incl_colombia mean_pairwise_distance NaN NaN 0.2053 scaled weighted units
neotropics_incl_colombia pred_domain_area_mha 16.2884 2.4979 18.7863 Mha
neotropics_incl_colombia pred_domain_area_share 0.8670 0.1330 1.0000 fraction
neotropics_incl_colombia expected_area_uncal_mha 4.0477 0.5579 4.6056 Mha
neotropics_incl_colombia expected_area_prior_shift_mha 0.1142 0.0137 0.1280 Mha
neotropics_incl_colombia area_p_gt05_uncal_mha 1.2878 0.0596 1.3474 Mha
neotropics_incl_colombia mean_p_grid_area_weighted 0.2485 0.2234 0.2452 p
neotropics_incl_colombia authors_expected_area_mha 9.2838 1.0667 10.3505 Mha
neotropics_incl_colombia authors_area_pct_gt50_mha 10.2141 0.8705 11.0846 Mha
neotropics_incl_colombia validation_accuracy_2000 0.7750 0.8562 0.7835 fraction
neotropics_incl_colombia validation_accuracy_regrowth_2000 0.6476 0.5765 0.6431 fraction
neotropics_incl_colombia validation_accuracy_nonregrowth_2000 0.9152 0.9740 0.9239 fraction
neotropics_incl_colombia validation_balanced_accuracy_2000 0.7814 0.7752 0.7835 fraction
neotropics_incl_colombia validation_n 110418.0000 12938.0000 123356.0000 points
neotropics_incl_colombia validation_share_regrowth 0.5239 0.2964 0.5000 fraction
neotropics_incl_colombia nonregrowth_n_2000 52575.0000 9103.0000 61678.0000 points
neotropics_incl_colombia nonregrowth_mean_p_model_2000 0.2496 0.2215 0.2455 p
neotropics_incl_colombia nonregrowth_share_gt05_model_2000 0.0848 0.0260 0.0761 fraction
neotropics_incl_colombia nonregrowth_mean_p_authors_aoa2000 0.5366 0.4161 0.5188 p
neotropics_incl_colombia nonregrowth_share_gt05_authors_aoa2000 0.5615 0.3229 0.5263 fraction
neotropics_incl_colombia nonregrowth_n_2018 51965.0000 9713.0000 61678.0000 points
neotropics_incl_colombia nonregrowth_mean_p_model_2018 0.2339 0.2233 0.2322 p
neotropics_incl_colombia nonregrowth_share_gt05_model_2018 0.0652 0.0356 0.0605 fraction
neotropics_incl_colombia nonregrowth_mean_p_authors_aoa2018 0.5375 0.4188 0.5188 p
neotropics_incl_colombia nonregrowth_share_gt05_authors_aoa2018 0.5633 0.3282 0.5263 fraction
6. DI and accuracy (Meyer & Pebesma 2021)
Accuracy by DI decile for (i) the Colombian validation points under each model (for the Neotropical models these are the diagnostic-3 transfer points) and (ii) cross-validated predictions on each model’s training draw with the primary HEALPix folds: each fold model is fitted on the other folds (same settings), and the DI of a held-out point is its CAST training DI.
The class mix changes strongly with DI (regrowth points are close to forest and to each other in predictor space; high-DI points are mostly non-regrowth), so plain accuracy by DI mixes a class effect with a dissimilarity effect. Accuracy per class and balanced accuracy are reported alongside.
P_CV = {}
for k, t in TRAIN.items():
    t = t.reset_index(drop=True)
    X, y, f = t[FINAL_VARS].to_numpy(), t.label.to_numpy(), FOLDS[k][PRIMARY]
    p = np.empty(len(t))
    for i in np.unique(f):
        te = f == i
        p[te] = make_rf(seed=SEED + int(i)).fit(X[~te], y[~te]).predict_proba(X[te])[:, 1]
    P_CV[k] = (p, y)
    print(f"{k:26s} CV ({PRIMARY}) accuracy {((p > 0.5) == y).mean():.4f}")

N_BINS = 5 if SMOKE else 10
bin_rows = []
SETS = {}
for k in MODELS:
    SETS[(k, "colombia_validation_2000")] = (DI_VAL[k], P_VAL[k], y_val)
    SETS[(k, f"cv_heldout_{PRIMARY}")] = (AOAS[k].train_di[PRIMARY], *P_CV[k])
for (k, pset), (di, p, y) in SETS.items():
    thr = AOAS[k].thresholds[PRIMARY]
    edges = np.unique(np.quantile(di, np.linspace(0, 1, N_BINS + 1)))
    b = np.clip(np.searchsorted(edges, di, side="right") - 1, 0, len(edges) - 2)
    for i in range(len(edges) - 1):
        s = b == i
        if s.any():
            bin_rows.append(dict(model=k, point_set=pset, bin=i, di_lo=edges[i], di_hi=edges[i + 1],
                                 di_mean=float(di[s].mean()), n=int(s.sum()),
                                 **class_acc((p[s] > 0.5) == y[s], y[s]), share_regrowth=float(y[s].mean()),
                                 share_outside_aoa=float((di[s] > thr).mean()), threshold=thr))
    ins = di <= thr
    for lab, s in [("inside_aoa", ins), ("outside_aoa", ~ins), ("all", np.ones_like(ins))]:
        if s.any():
            bin_rows.append(dict(model=k, point_set=pset, bin=lab, di_lo=float(di[s].min()), di_hi=float(di[s].max()),
                                 di_mean=float(di[s].mean()), n=int(s.sum()),
                                 **class_acc((p[s] > 0.5) == y[s], y[s]), share_regrowth=float(y[s].mean()),
                                 share_outside_aoa=float((~ins[s]).mean()), threshold=thr))
di_acc = pd.DataFrame(bin_rows)
di_acc.to_csv(RESULTS / "aoa_di_accuracy.csv", index=False)
with pd.option_context("display.width", 250, "display.max_rows", 200):
    print(di_acc.to_string(index=False, float_format=lambda v: f"{v:.4f}"))
colombia CV (healpix_d6) accuracy 0.8561
neotropics_excl_colombia CV (healpix_d6) accuracy 0.8344
neotropics_incl_colombia CV (healpix_d6) accuracy 0.8285
model point_set bin di_lo di_hi di_mean n accuracy accuracy_regrowth accuracy_nonregrowth balanced_accuracy share_regrowth share_outside_aoa threshold
colombia colombia_validation_2000 0 0.0000 0.0212 0.0135 12336 0.9772 0.9931 0.5158 0.7545 0.9667 0.0000 0.1979
colombia colombia_validation_2000 1 0.0212 0.0315 0.0263 12335 0.9245 0.9723 0.5948 0.7835 0.8734 0.0000 0.1979
colombia colombia_validation_2000 2 0.0315 0.0421 0.0368 12336 0.8705 0.9170 0.7452 0.8311 0.7296 0.0000 0.1979
colombia colombia_validation_2000 3 0.0421 0.0517 0.0469 12335 0.8469 0.8534 0.8374 0.8454 0.5901 0.0000 0.1979
colombia colombia_validation_2000 4 0.0517 0.0613 0.0565 12336 0.8419 0.7820 0.8953 0.8387 0.4711 0.0000 0.1979
colombia colombia_validation_2000 5 0.0613 0.0715 0.0663 12335 0.8441 0.7164 0.9287 0.8226 0.3985 0.0000 0.1979
colombia colombia_validation_2000 6 0.0715 0.0836 0.0773 12336 0.8645 0.6806 0.9510 0.8158 0.3200 0.0000 0.1979
colombia colombia_validation_2000 7 0.0836 0.0995 0.0912 12335 0.8753 0.6400 0.9621 0.8010 0.2693 0.0000 0.1979
colombia colombia_validation_2000 8 0.0995 0.1257 0.1110 12336 0.8960 0.6205 0.9727 0.7966 0.2179 0.0000 0.1979
colombia colombia_validation_2000 9 0.1257 2.6689 0.1665 12336 0.9259 0.6357 0.9826 0.8091 0.1633 0.1524 0.1979
colombia colombia_validation_2000 inside_aoa 0.0000 0.1979 0.0664 121476 0.8859 0.8540 0.9185 0.8863 0.5058 0.0000 0.1979
colombia colombia_validation_2000 outside_aoa 0.1980 2.6689 0.2541 1880 0.9367 0.5830 0.9872 0.7851 0.1250 1.0000 0.1979
colombia colombia_validation_2000 all 0.0000 2.6689 0.0692 123356 0.8867 0.8530 0.9204 0.8867 0.5000 0.0152 0.1979
colombia cv_heldout_healpix_d6 0 0.0030 0.0338 0.0251 3953 0.9583 0.9858 0.5172 0.7515 0.9413 0.0000 0.1979
colombia cv_heldout_healpix_d6 1 0.0338 0.0477 0.0410 3952 0.8697 0.9027 0.7387 0.8207 0.7986 0.0000 0.1979
colombia cv_heldout_healpix_d6 2 0.0477 0.0595 0.0539 3951 0.8008 0.7975 0.8069 0.8022 0.6462 0.0000 0.1979
colombia cv_heldout_healpix_d6 3 0.0595 0.0698 0.0647 3953 0.7933 0.6998 0.8916 0.7957 0.5123 0.0000 0.1979
colombia cv_heldout_healpix_d6 4 0.0698 0.0799 0.0748 3952 0.8138 0.6942 0.9140 0.8041 0.4560 0.0000 0.1979
colombia cv_heldout_healpix_d6 5 0.0799 0.0910 0.0854 3951 0.8426 0.6924 0.9468 0.8196 0.4098 0.0000 0.1979
colombia cv_heldout_healpix_d6 6 0.0910 0.1040 0.0972 3953 0.8492 0.6594 0.9504 0.8049 0.3476 0.0000 0.1979
colombia cv_heldout_healpix_d6 7 0.1040 0.1206 0.1119 3952 0.8611 0.6576 0.9595 0.8085 0.3259 0.0000 0.1979
colombia cv_heldout_healpix_d6 8 0.1206 0.1486 0.1331 3952 0.8783 0.6829 0.9646 0.8238 0.3064 0.0000 0.1979
colombia cv_heldout_healpix_d6 9 0.1486 3.2022 0.1966 3953 0.8940 0.6650 0.9728 0.8189 0.2560 0.3018 0.1979
colombia cv_heldout_healpix_d6 inside_aoa 0.0030 0.1979 0.0830 38329 0.8541 0.7907 0.9200 0.8554 0.5095 0.0000 0.1979
colombia cv_heldout_healpix_d6 outside_aoa 0.1979 3.2022 0.2619 1193 0.9195 0.6623 0.9813 0.8218 0.1936 1.0000 0.1979
colombia cv_heldout_healpix_d6 all 0.0030 3.2022 0.0884 39522 0.8561 0.7892 0.9230 0.8561 0.5000 0.0302 0.1979
neotropics_excl_colombia colombia_validation_2000 0 0.0076 0.0542 0.0411 12336 0.7961 0.7995 0.7678 0.7836 0.8942 0.0000 0.1630
neotropics_excl_colombia colombia_validation_2000 1 0.0542 0.0740 0.0642 12335 0.7272 0.6882 0.8402 0.7642 0.7433 0.0000 0.1630
neotropics_excl_colombia colombia_validation_2000 2 0.0740 0.0925 0.0833 12336 0.7166 0.5848 0.9019 0.7433 0.5843 0.0000 0.1630
neotropics_excl_colombia colombia_validation_2000 3 0.0925 0.1102 0.1014 12335 0.7394 0.5304 0.9395 0.7350 0.4891 0.0000 0.1630
neotropics_excl_colombia colombia_validation_2000 4 0.1102 0.1267 0.1186 12336 0.7450 0.4671 0.9538 0.7105 0.4292 0.0000 0.1630
neotropics_excl_colombia colombia_validation_2000 5 0.1267 0.1414 0.1342 12335 0.7323 0.3988 0.9741 0.6865 0.4203 0.0000 0.1630
neotropics_excl_colombia colombia_validation_2000 6 0.1414 0.1564 0.1487 12336 0.7411 0.3900 0.9805 0.6853 0.4055 0.0000 0.1630
neotropics_excl_colombia colombia_validation_2000 7 0.1564 0.1748 0.1651 12335 0.8075 0.4589 0.9858 0.7223 0.3383 0.6022 0.1630
neotropics_excl_colombia colombia_validation_2000 8 0.1748 0.2072 0.1890 12336 0.8547 0.5479 0.9854 0.7667 0.2987 1.0000 0.1630
neotropics_excl_colombia colombia_validation_2000 9 0.2072 1.1777 0.2763 12336 0.8108 0.5590 0.9766 0.7678 0.3970 1.0000 0.1630
neotropics_excl_colombia colombia_validation_2000 inside_aoa 0.0076 0.1630 0.1021 91256 0.7447 0.5874 0.9410 0.7642 0.5551 0.0000 0.1630
neotropics_excl_colombia colombia_validation_2000 outside_aoa 0.1630 1.1777 0.2178 32100 0.8306 0.5400 0.9827 0.7613 0.3435 1.0000 0.1630
neotropics_excl_colombia colombia_validation_2000 all 0.0076 1.1777 0.1322 123356 0.7671 0.5789 0.9552 0.7671 0.5000 0.2602 0.1630
neotropics_excl_colombia cv_heldout_healpix_d6 0 0.0022 0.0266 0.0187 3953 0.9211 0.9428 0.7845 0.8637 0.8626 0.0000 0.1630
neotropics_excl_colombia cv_heldout_healpix_d6 1 0.0266 0.0363 0.0316 3952 0.8477 0.8411 0.8621 0.8516 0.6880 0.0000 0.1630
neotropics_excl_colombia cv_heldout_healpix_d6 2 0.0363 0.0452 0.0407 3951 0.8193 0.7728 0.8908 0.8318 0.6059 0.0000 0.1630
neotropics_excl_colombia cv_heldout_healpix_d6 3 0.0452 0.0535 0.0494 3953 0.8143 0.7388 0.9115 0.8251 0.5626 0.0000 0.1630
neotropics_excl_colombia cv_heldout_healpix_d6 4 0.0535 0.0619 0.0577 3952 0.8039 0.6863 0.9193 0.8028 0.4952 0.0000 0.1630
neotropics_excl_colombia cv_heldout_healpix_d6 5 0.0619 0.0714 0.0665 3952 0.8054 0.6450 0.9350 0.7900 0.4469 0.0000 0.1630
neotropics_excl_colombia cv_heldout_healpix_d6 6 0.0714 0.0827 0.0770 3952 0.7983 0.5836 0.9495 0.7666 0.4132 0.0000 0.1630
neotropics_excl_colombia cv_heldout_healpix_d6 7 0.0827 0.0981 0.0898 3952 0.8148 0.5745 0.9624 0.7684 0.3806 0.0000 0.1630
neotropics_excl_colombia cv_heldout_healpix_d6 8 0.0981 0.1231 0.1093 3952 0.8434 0.5597 0.9741 0.7669 0.3155 0.0000 0.1630
neotropics_excl_colombia cv_heldout_healpix_d6 9 0.1231 31.8635 0.1852 3953 0.8758 0.5160 0.9829 0.7495 0.2294 0.3666 0.1630
neotropics_excl_colombia cv_heldout_healpix_d6 inside_aoa 0.0022 0.1630 0.0653 38073 0.8312 0.7340 0.9334 0.8337 0.5124 0.0000 0.1630
neotropics_excl_colombia cv_heldout_healpix_d6 outside_aoa 0.1630 31.8635 0.2640 1449 0.9186 0.5595 0.9942 0.7768 0.1739 1.0000 0.1630
neotropics_excl_colombia cv_heldout_healpix_d6 all 0.0022 31.8635 0.0726 39522 0.8344 0.7317 0.9370 0.8344 0.5000 0.0367 0.1630
neotropics_incl_colombia colombia_validation_2000 0 0.0000 0.0464 0.0358 12336 0.8042 0.8199 0.7445 0.7822 0.7913 0.0000 0.1837
neotropics_incl_colombia colombia_validation_2000 1 0.0464 0.0590 0.0531 12335 0.7758 0.7593 0.8164 0.7879 0.7111 0.0000 0.1837
neotropics_incl_colombia colombia_validation_2000 2 0.0590 0.0701 0.0646 12336 0.7572 0.6988 0.8551 0.7769 0.6262 0.0000 0.1837
neotropics_incl_colombia colombia_validation_2000 3 0.0701 0.0815 0.0757 12335 0.7345 0.6149 0.8870 0.7509 0.5604 0.0000 0.1837
neotropics_incl_colombia colombia_validation_2000 4 0.0815 0.0944 0.0877 12336 0.7402 0.5513 0.9121 0.7317 0.4764 0.0000 0.1837
neotropics_incl_colombia colombia_validation_2000 5 0.0944 0.1090 0.1014 12336 0.7549 0.5094 0.9370 0.7232 0.4260 0.0000 0.1837
neotropics_incl_colombia colombia_validation_2000 6 0.1090 0.1269 0.1176 12335 0.7771 0.5072 0.9535 0.7303 0.3953 0.0000 0.1837
neotropics_incl_colombia colombia_validation_2000 7 0.1269 0.1502 0.1379 12335 0.8146 0.5496 0.9648 0.7572 0.3618 0.0000 0.1837
neotropics_incl_colombia colombia_validation_2000 8 0.1502 0.1862 0.1663 12336 0.8192 0.5471 0.9701 0.7586 0.3568 0.0488 0.1837
neotropics_incl_colombia colombia_validation_2000 9 0.1862 1.0117 0.2388 12336 0.8575 0.5789 0.9739 0.7764 0.2947 1.0000 0.1837
neotropics_incl_colombia colombia_validation_2000 inside_aoa 0.0000 0.1837 0.0928 110418 0.7750 0.6476 0.9152 0.7814 0.5239 0.0000 0.1837
neotropics_incl_colombia colombia_validation_2000 outside_aoa 0.1837 1.0117 0.2363 12938 0.8562 0.5765 0.9740 0.7752 0.2964 1.0000 0.1837
neotropics_incl_colombia colombia_validation_2000 all 0.0000 1.0117 0.1079 123356 0.7835 0.6431 0.9239 0.7835 0.5000 0.1049 0.1837
neotropics_incl_colombia cv_heldout_healpix_d6 0 0.0027 0.0301 0.0217 3953 0.9233 0.9471 0.7825 0.8648 0.8558 0.0000 0.1837
neotropics_incl_colombia cv_heldout_healpix_d6 1 0.0301 0.0412 0.0358 3952 0.8639 0.8715 0.8458 0.8586 0.7047 0.0000 0.1837
neotropics_incl_colombia cv_heldout_healpix_d6 2 0.0412 0.0507 0.0460 3951 0.8297 0.7959 0.8836 0.8398 0.6150 0.0000 0.1837
neotropics_incl_colombia cv_heldout_healpix_d6 3 0.0507 0.0598 0.0552 3952 0.8085 0.7341 0.8949 0.8145 0.5377 0.0000 0.1837
neotropics_incl_colombia cv_heldout_healpix_d6 4 0.0598 0.0692 0.0645 3953 0.7946 0.6729 0.9184 0.7956 0.5042 0.0000 0.1837
neotropics_incl_colombia cv_heldout_healpix_d6 5 0.0692 0.0798 0.0743 3951 0.7793 0.5919 0.9335 0.7627 0.4515 0.0000 0.1837
neotropics_incl_colombia cv_heldout_healpix_d6 6 0.0798 0.0928 0.0860 3953 0.7852 0.5532 0.9442 0.7487 0.4065 0.0000 0.1837
neotropics_incl_colombia cv_heldout_healpix_d6 7 0.0928 0.1113 0.1014 3952 0.8047 0.5455 0.9499 0.7477 0.3591 0.0000 0.1837
neotropics_incl_colombia cv_heldout_healpix_d6 8 0.1113 0.1458 0.1262 3952 0.8388 0.5650 0.9559 0.7605 0.2996 0.0000 0.1837
neotropics_incl_colombia cv_heldout_healpix_d6 9 0.1458 14.0643 0.2092 3953 0.8571 0.6660 0.9263 0.7961 0.2659 0.5065 0.1837
neotropics_incl_colombia cv_heldout_healpix_d6 inside_aoa 0.0027 0.1837 0.0728 37520 0.8273 0.7370 0.9221 0.8296 0.5121 0.0000 0.1837
neotropics_incl_colombia cv_heldout_healpix_d6 outside_aoa 0.1837 14.0643 0.2543 2002 0.8506 0.7185 0.9003 0.8094 0.2732 1.0000 0.1837
neotropics_incl_colombia cv_heldout_healpix_d6 all 0.0027 14.0643 0.0820 39522 0.8285 0.7365 0.9205 0.8285 0.5000 0.0507 0.1837
7. HEALPix depth-8 share of the prediction domain outside the AOA (WGS84)
g["cell"] = lonlat_to_healpix(g.lon.to_numpy(), g.lat.to_numpy(), HP_DEPTH, ellipsoid="WGS84")
cols = {"pred_area": a_grid}
for k in MODELS:
    cols[f"outside_area_{k}"] = a_grid * (DI_GRID[k] > AOAS[k].thresholds[PRIMARY])
    cols[f"di_x_area_{k}"] = a_grid * DI_GRID[k]
cells = pd.DataFrame(cols).groupby(g.cell.to_numpy()).sum()
cell_ids = cells.index.to_numpy().astype("uint64")
lon_c, lat_c = healpix_to_lonlat(cell_ids, HP_DEPTH, ellipsoid="WGS84")
data_vars = {"pred_area": ("cells", cells.pred_area.to_numpy(),
                           {"units": "m2", "long_name": "prediction-domain area with complete predictors"})}
for k in MODELS:
    data_vars[f"outside_area_{k}"] = ("cells", cells[f"outside_area_{k}"].to_numpy(),
                                      {"units": "m2", "long_name": f"area outside the AOA, {MODEL_LABELS[k]} model"})
    data_vars[f"share_outside_{k}"] = ("cells", (cells[f"outside_area_{k}"] / cells.pred_area).to_numpy(),
                                       {"units": "1", "long_name": f"share outside the AOA, {MODEL_LABELS[k]} model",
                                        "threshold": AOAS[k].thresholds[PRIMARY]})
    data_vars[f"mean_di_{k}"] = ("cells", (cells[f"di_x_area_{k}"] / cells.pred_area).to_numpy(),
                                 {"units": "1", "long_name": f"area-weighted mean DI, {MODEL_LABELS[k]} model"})
ds = xr.Dataset(data_vars,
                coords={"cell_ids": ("cells", cell_ids, {"grid_name": "healpix", "level": HP_DEPTH,
                                                         "indexing_scheme": "nested", "ellipsoid": "WGS84"}),
                        "longitude": ("cells", (np.asarray(lon_c) + 180) % 360 - 180),
                        "latitude": ("cells", np.asarray(lat_c))},
                attrs={"title": "Area of applicability (Meyer & Pebesma 2021, CAST port) of the step-2 and diagnostic-3 "
                                "models over the Colombian prediction domain, HEALPix depth 8",
                       "method": f"1-in-100 systematic 30 m grid, 2018/2015 inputs; exact WGS84 pixel area x 100; "
                                 f"threshold from CV training DI with HEALPix depth-{FOLD_DEPTH} folds"})
ds.to_netcdf(RESULTS / "aoa_healpix_d8.nc")
print(ds)
<xarray.Dataset> Size: 170kB
Dimensions: (cells: 1635)
Coordinates:
cell_ids (cells) uint64 13kB 478916 ... 51...
longitude (cells) float64 13kB -69.96 ... -...
latitude (cells) float64 13kB -4.351 ... 1...
Dimensions without coordinates: cells
Data variables:
pred_area (cells) float64 13kB 6.138e+05 .....
outside_area_colombia (cells) float64 13kB 3.836e+05 .....
share_outside_colombia (cells) float64 13kB 0.625 ... 0....
mean_di_colombia (cells) float64 13kB 0.2431 ... 0...
outside_area_neotropics_excl_colombia (cells) float64 13kB 7.673e+04 .....
share_outside_neotropics_excl_colombia (cells) float64 13kB 0.125 ... 0.0
mean_di_neotropics_excl_colombia (cells) float64 13kB 0.1216 ... 0...
outside_area_neotropics_incl_colombia (cells) float64 13kB 0.0 ... 0.0
share_outside_neotropics_incl_colombia (cells) float64 13kB 0.0 ... 0.0
mean_di_neotropics_incl_colombia (cells) float64 13kB 0.1214 ... 0...
Attributes:
title: Area of applicability (Meyer & Pebesma 2021, CAST port) of the ...
method: 1-in-100 systematic 30 m grid, 2018/2015 inputs; exact WGS84 pi...
8. Figure
def cell_polys(ids: np.ndarray) -> list[np.ndarray]:
    lo, la = vertices(ids.astype("uint64"), HP_DEPTH, ellipsoid="WGS84")
    lo = (np.asarray(lo) + 180) % 360 - 180
    return [np.column_stack([a, b]) for a, b in zip(lo, np.asarray(la))]


polys = cell_polys(cell_ids)
fig = plt.figure(figsize=(18, 11))
gs = fig.add_gridspec(2, 3, height_ratios=[1.3, 1])
for i, k in enumerate(MODELS):
    ax = fig.add_subplot(gs[0, i])
    pc = PolyCollection(polys, array=ds[f"share_outside_{k}"].to_numpy(), cmap="magma_r", edgecolor="none")
    pc.set_clim(0, 1)
    ax.add_collection(pc)
    ax.autoscale_view()
    ax.set_aspect("equal")
    share = summary.query("model == @k and cv_folds == @PRIMARY and metric == 'pred_domain_area_share'").outside.iloc[0]
    ax.set_title(f"{MODEL_LABELS[k]}: share outside AOA\n(domain total {share:.1%}, HEALPix d8)", fontsize=10)
fig.colorbar(pc, ax=fig.axes[:3], shrink=0.8, label="share of prediction-domain area outside the AOA")
for j, pset in enumerate(["colombia_validation_2000", f"cv_heldout_{PRIMARY}"]):
    ax = fig.add_subplot(gs[1, j])
    for i, k in enumerate(MODELS):
        d = di_acc[(di_acc.model == k) & (di_acc.point_set == pset) & ~di_acc.bin.isin(["inside_aoa", "outside_aoa", "all"])]
        ax.plot(d.di_mean, d.balanced_accuracy, "o-", color=f"C{i}", label=MODEL_LABELS[k])
        ax.plot(d.di_mean, d.accuracy, "x:", color=f"C{i}", alpha=0.6)
        ax.axvline(AOAS[k].thresholds[PRIMARY], color=f"C{i}", ls=":", lw=1)
    ax.set_xscale("log")
    ax.set_xlabel("dissimilarity index (decile mean; dotted = AOA threshold)")
    ax.set_ylabel("balanced accuracy (o-); accuracy (x:)")
    ax.set_title("Colombian validation points (2000 inputs)" if j == 0 else f"Cross-validated, {PRIMARY} folds",
                 fontsize=10)
    ax.legend(fontsize=8)
ax = fig.add_subplot(gs[1, 2])
sub = summary[(summary.cv_folds == PRIMARY) & (summary.metric == "validation_balanced_accuracy_2000")].set_index("model")
x = np.arange(len(sub))
ax.bar(x - 0.2, sub.inside, 0.4, label="inside AOA")
ax.bar(x + 0.2, sub.outside, 0.4, label="outside AOA")
ax.set_xticks(x, [MODEL_LABELS[k].replace(" ", "\n", 1) for k in sub.index], fontsize=8)
ax.set_ylim(0.5, 1)
ax.set_ylabel("Colombian validation balanced accuracy")
ax.set_title("Balanced accuracy inside vs outside the AOA", fontsize=10)
ax.legend(fontsize=8)
fig.savefig(FIGURES / "aoa_colombia.png", dpi=150, bbox_inches="tight")
plt.show()